
Know before you run. Because APIs don't care about your money.





NoRefund is a free, open-source, desktop-first utility for AI engineers. It counts tokens in documents (PDF, PPTX, DOCX, TXT, MD) as well as folders and estimates the cost of running them through any major LLM - before you make a single API call. Analysis is 100% local: your documents never leave your machine. Network access is used only when you explicitly download a tokenizer or refresh currency rates.
Most online token counters ask you to paste your text into a website. That is fine for a short paragraph, but not for a client contract, an internal report, or anything you are not supposed to hand to a random server. Here is where that actually shows up in real work.
- Before building a pipeline that reads documents automatically. Check whether a batch of files will actually fit inside a model's context window before writing a single line of chunking code.
- Before the API bill gets bigger than planned. Estimate the cost of processing a whole folder of reports across a few different models, and pick the cheapest one that still does the job.
- When the documents are confidential. Legal contracts, HR files, financial reports, anything you would not paste into a public website, can still be measured accurately and privately.
- When choosing between providers. Compare OpenAI, Anthropic, Google, and other providers side by side on the exact same document, sorted by price, instead of guessing from memory.
- A quick check before a demo or a deadline. Five minutes before presenting, you want a straight answer: will this file actually fit, or will the model cut it off halfway through?
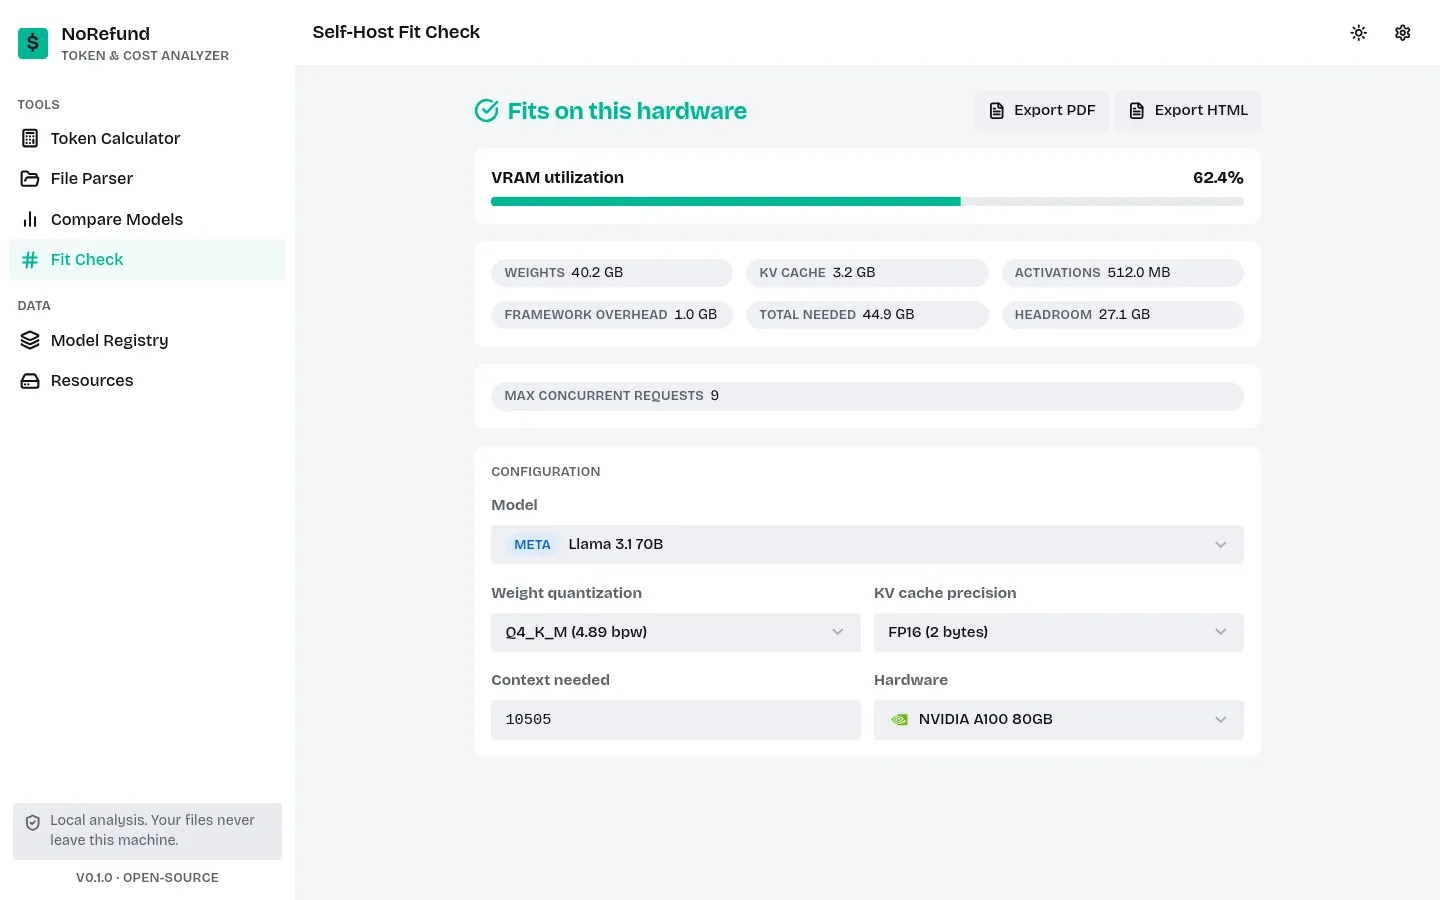
- Before renting or buying a GPU to self-host a model. Fit Check estimates whether an open-weight model's weights, KV cache, and activations actually fit in a given card's VRAM before you commit to hardware.
- Parse any PDF, PPTX, DOCX, TXT, MD files single or select a directory.
- Count tokens against real tokenizers for 21 models across 7 providers (Count may vary as software develops and we add more models)
- Context window usage and fit/chunk analysis
- Compare cost and context fit across multiple models, with portfolio cost projection
- Self-Host Fit Check: does an open-weight model fit on your own GPU, Apple Silicon Mac, or cloud instance?
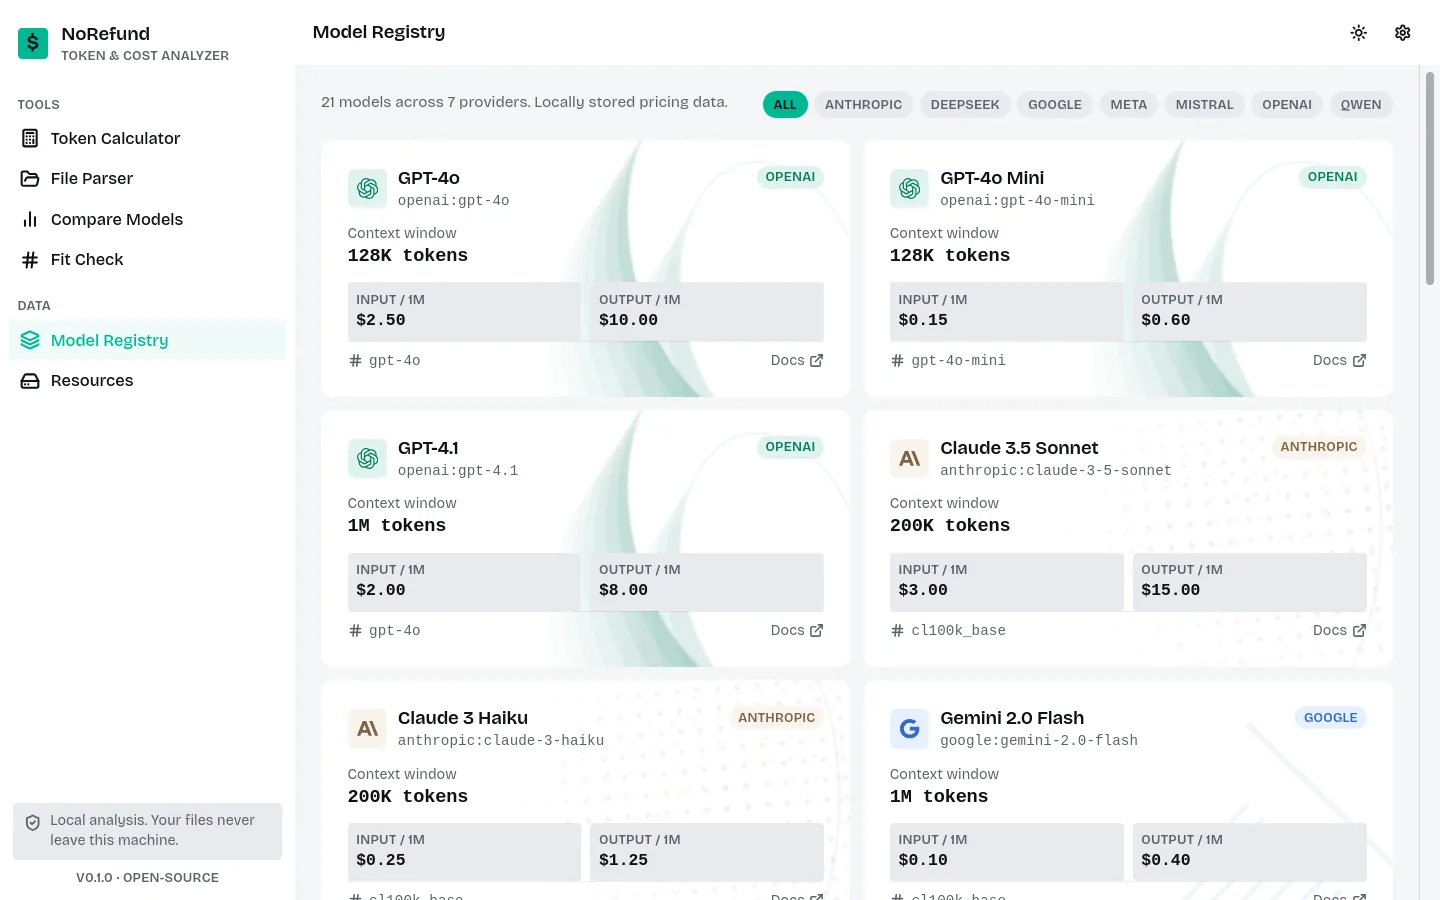
- Model Registry: browse every supported model's context window, pricing, and architecture
- Resources view: manage downloaded tokenizers, one-click download for anything missing
- CLI and a native desktop app (React + pywebview) for Windows, macOS, and Linux
Built with Python, React, TypeScript, and pywebview.
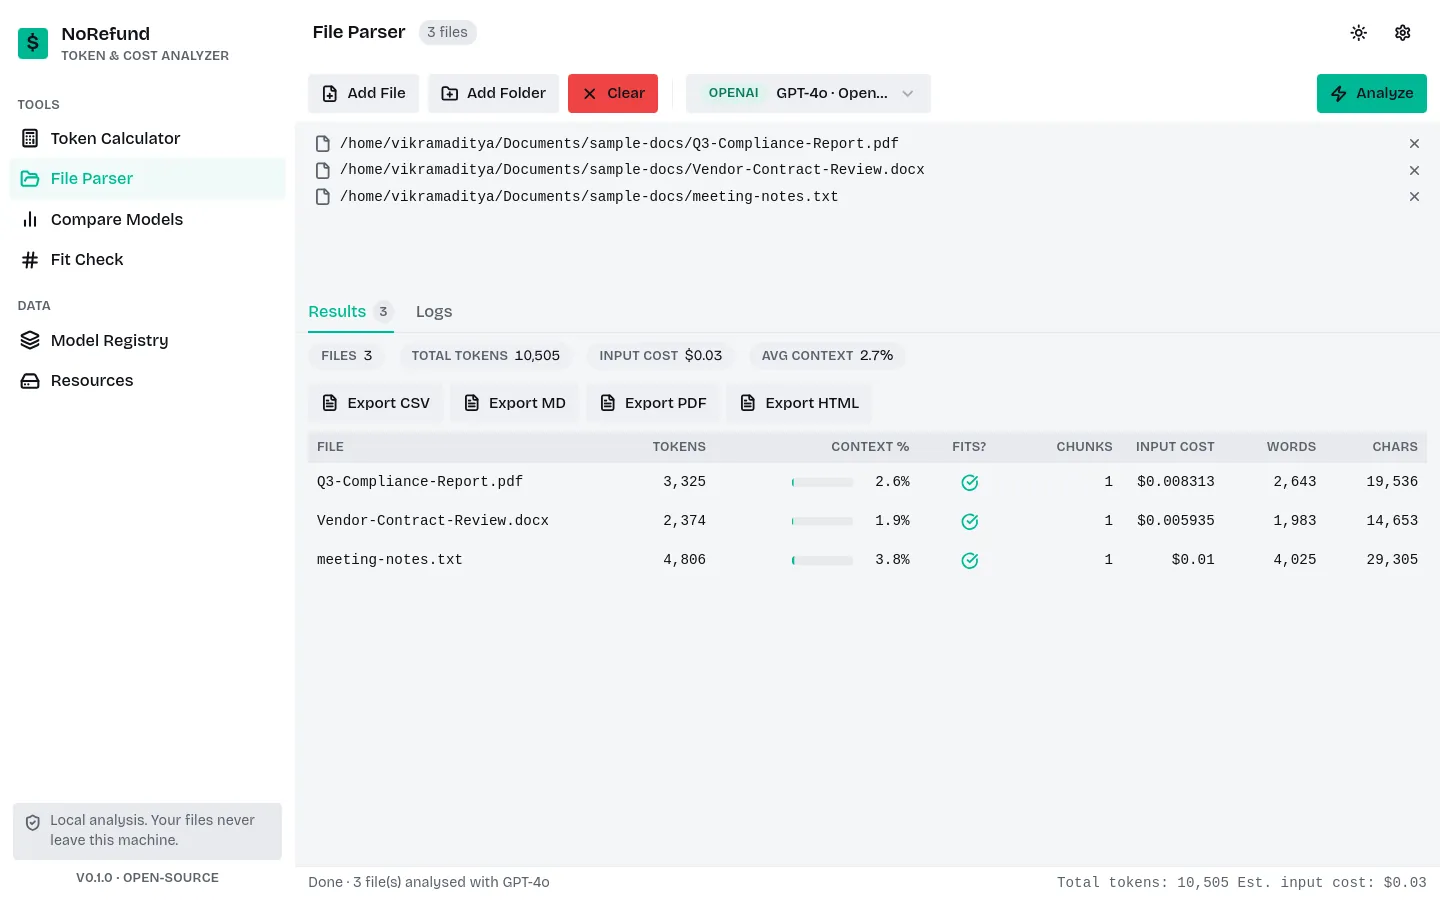
File Parser — analyze a whole folder against a chosen model: token count, context fit, chunk count, and cost per file.
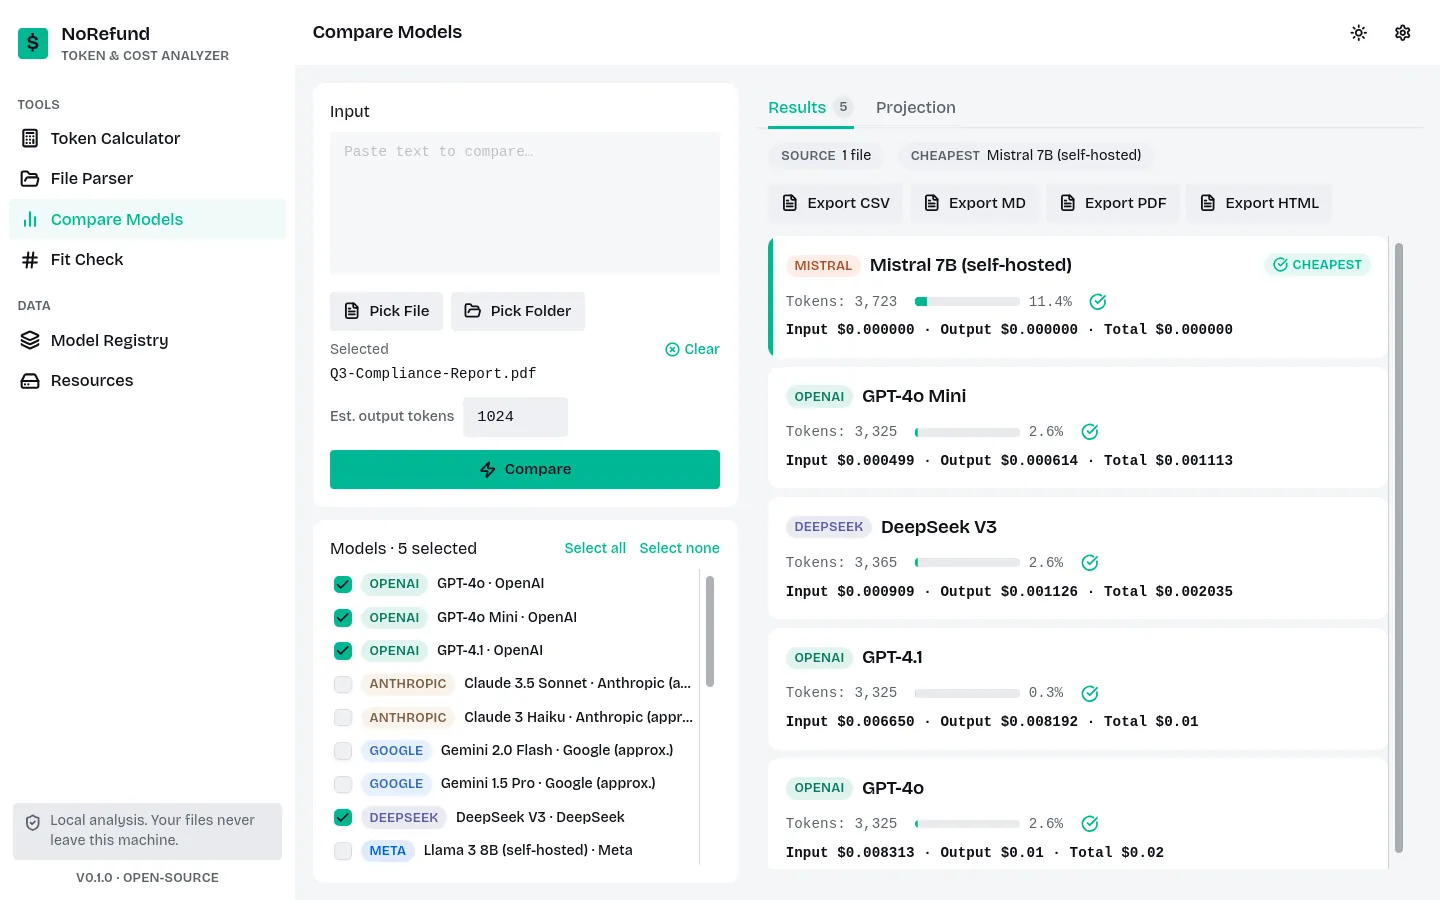
Compare Models — the same document across every supported model, ranked cheapest first.
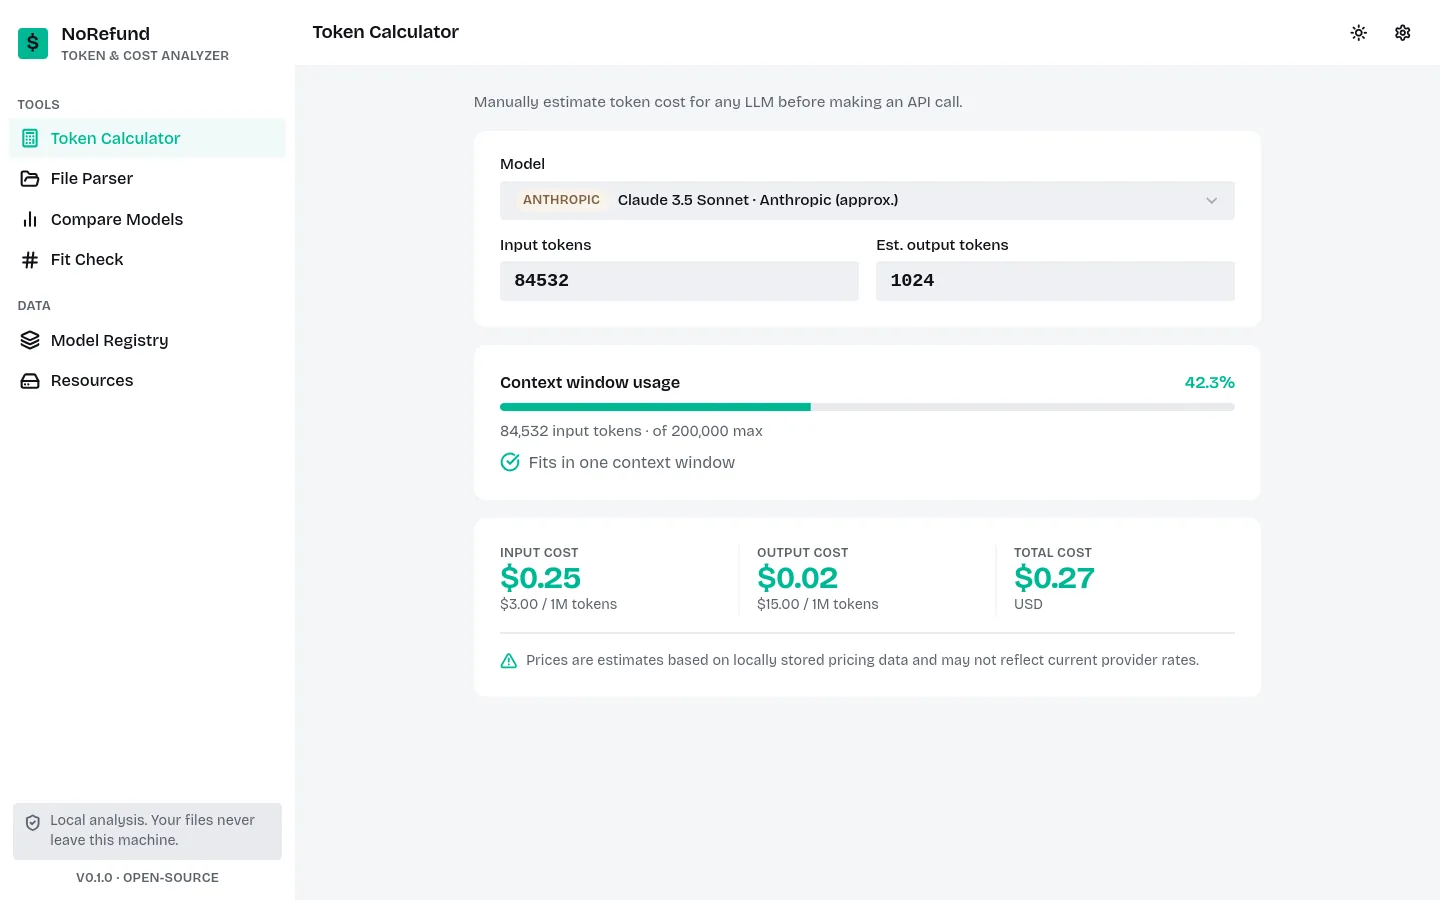
Token Calculator — context bar and full cost breakdown for a single input.
Model Registry — every supported model's context window, price, and architecture, filterable by provider.
Self-Host Fit Check — estimate GPU VRAM headroom for an open-weight model before you commit to hardware.
Prebuilt Windows, macOS, and Linux builds are on the Releases page — no Python install required.
Windows SmartScreen: NoRefund isn't code-signed yet, so Windows shows a "Windows protected your PC" warning the first time you run it. Click More info → Run anyway to continue.
macOS Gatekeeper: for the same reason, macOS may refuse to open the app with an
"is damaged and can't be opened" dialog. Run xattr -cr NoRefund.app in Terminal after
extracting it — see packaging/README.md for details.
For the CLI on any platform with Python 3.12+:
pip install norefund
norefund path/to/file.pdf --model openai:gpt-4o# Install
pip install -e ".[dev]"
cd frontend && npm install && npm run build && cd ..
# CLI
norefund path/to/file.pdf --model openai:gpt-5.6-sol
# Desktop app
norefund --guiFor hot-reloading frontend development, see Contributing.
| Doc | What's in it |
|---|---|
| Architecture | How core/desktop/frontend fit together, the bridge contract, request flow |
| Mathematics | Every cost, context-fit, and self-host memory formula, derived |
| Data Sources | Where model pricing & architecture data comes from, and how it's verified |
| Adding a Model | Field-by-field guide to adding or fixing a registry entry (pure YAML, no code) |
| Project Structure | Directory-by-directory map of the repo |
| Contributing | Dev setup, conventions, tests, how to open a PR |
NoRefund is open source and welcomes contributions. New issues and feature requests are always open — see the issue tracker to report a bug or suggest something, and Contributing to get started on a PR.
MIT — see LICENSE