Repository navigation
Generative AI Full Course Lecture 5 Hard vs Soft Masks and Differential Diffusion
Full tutorial link > https://www.youtube.com/watch?v=DJcgVASlg38
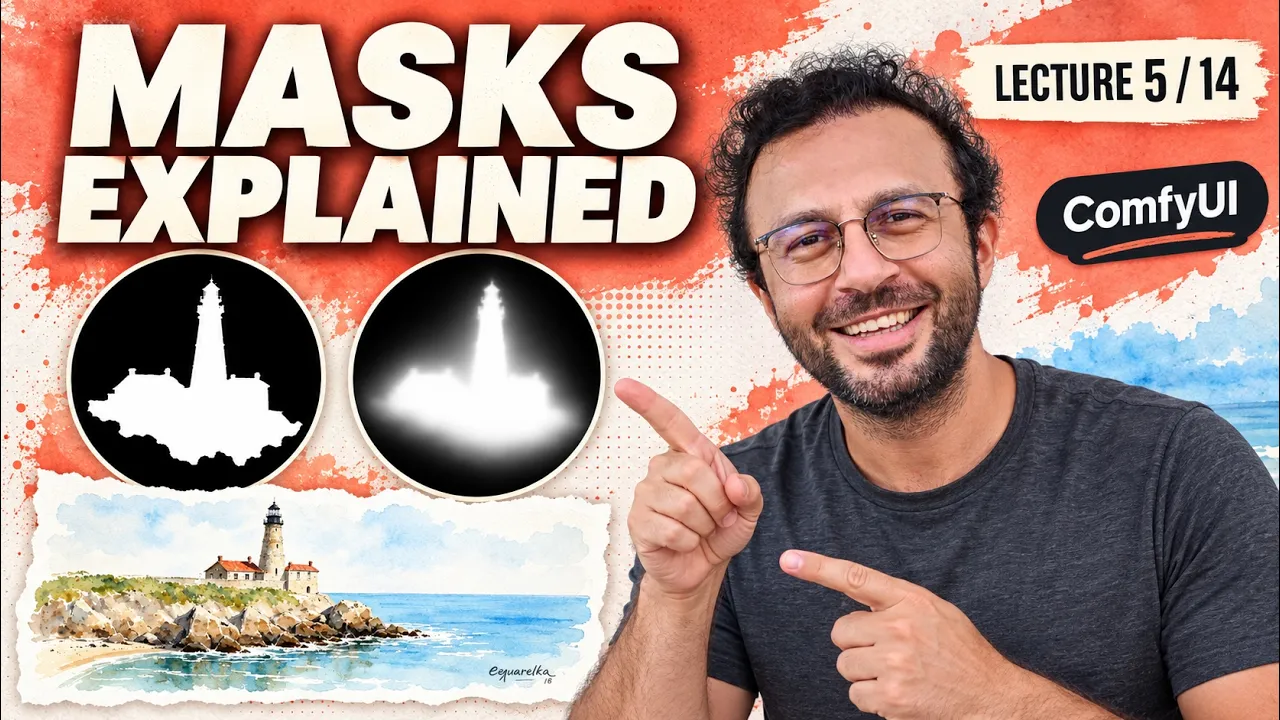



Choose where an image changes in ComfyUI. Lecture 5 of this 14-lecture course covers masks, inpainting, outpainting, SAM3 selection, face edits, transparent PNGs and editable layers on Windows.
🔗 Links:
Windows AI requirements guide: [ https://www.patreon.com/posts/111553210 ]
📦 Full course resource repository: [ https://github.com/FurkanGozukara/Generative-AI-Tools-And-Tecniques-2026-2027-Fall ]
📺 Full course playlist: [ https://www.youtube.com/playlist?list=PLUMEJUep1hiI ]
SECourses Discord: [ https://discord.com/invite/software-engineering-courses-secourses-772774097734074388 ]
🎯 You will learn how to paint and inspect masks, repair an invented signature, extend a scene, select objects with words, edit a face through Crop-and-Stitch, and place a transparent lantern over a background.
🧩 Main topics include Differential Diffusion, denoise, exact outside-region compositing, alpha polarity, Color Transfer and Qwen Image Layered.
Use the chapters to revisit each operation, setting group and comparison.
⏱️ Chapters:
00:00:00 Choose where an image changes
00:00:59 Update the existing ComfyUI installation
00:01:30 Activate the correct environment
00:01:43 Update source, packages and restart
00:02:26 Save the installation state before a custom node
00:03:30 Install Crop-and-Stitch from the Registry
00:04:48 Separate instruction editing from exact preservation
00:05:14 Sampling masks versus pixel composites
00:05:55 Paint and inspect a hard selection
00:06:22 Brush hardness, size and erasing
00:07:05 Mask pen versus image paint pen
00:07:19 Save and preview the actual mask
00:07:44 Compare brush hardness and selection edges
00:08:16 Alt-drag brush shortcut
00:08:42 Select a garment by colour
00:08:55 Tolerance and unwanted selections
00:09:51 Paint Bucket versus Color Select
00:10:59 Inspect the actual Week 3 signature
00:11:26 Cover every signature stroke
00:12:15 Build the masked latent path
00:12:29 VAE Encode and Set Latent Noise Mask
00:13:13 Fill prompt, fixed seed and denoise
00:14:24 Run and inspect the hard-mask repair
00:14:47 Inspect the repair boundary
00:15:27 Grow and blur the selection with Differential Diffusion
00:15:55 Blur radius, sigma and mask conversion
00:16:28 Connect Differential Diffusion
00:17:38 Compare the patch and restore outside pixels
00:18:06 Aligned before-and-after slider
00:18:19 Remaining fragments at denoise 0.75
00:18:33 Repeat both repairs at denoise 1.0
00:19:16 Composite onto the original pixels
00:19:39 Check outside the complete soft edge
00:20:22 Read a grey mask as a start-time map
00:20:56 Grey values and denoising strength
00:21:26 Run and inspect the ramp result
00:22:09 Extend a canvas with a matched editing graph
00:22:22 Padding, feathering and alignment
00:23:04 Run and inspect the extended scene
00:23:48 Preserve the original region
00:24:17 Load the segmentation model and its encoder
00:24:43 SAM3.1 download and loader wiring
00:25:37 Short phrases and token context
00:25:50 Select objects and inspect individual masks
00:26:19 Select the jacket by text
00:26:53 Individual windows and count limits
00:28:00 Detection threshold and refinement
00:28:30 Prepare a large photograph for a local edit
00:28:59 Glasses instruction and face mask
00:29:43 Inspect the whole-frame editing route
00:30:26 Run and inspect the whole-frame edit
00:31:10 Build and run the crop-and-stitch path
00:32:00 Crop context and output size
00:32:49 Mask expansion versus blend width
00:33:03 Connect and run Inpaint Stitch
00:34:03 Compare detail, timing and outside pixels
00:34:31 Actual timings and run conditions
00:34:45 Restore pixels outside the face edit
00:36:01 Generate a lantern with real transparency
00:36:57 Inspect light and dark backgrounds
00:37:31 Reload the saved transparent PNG
00:37:45 Trace opacity and inverted masks through the nodes
00:38:03 Invert the loader mask for compositing
00:38:48 Join Image with Alpha conventions
00:39:29 Place the transparent asset on a background
00:39:57 Offsets, source size and mask alignment
00:40:45 Generated alpha versus segmentation
00:41:55 Match colour and inspect alpha interpretation
00:42:20 Color Transfer method and strength
00:43:02 Straight versus premultiplied alpha
00:44:07 Prepare the separate layer-decomposition workflow
00:44:36 Layered model files and folders
00:45:43 Working resolution and layer count
00:46:37 Inspect and recombine the ordered RGBA layers
00:47:07 Composite the layers in order
00:47:50 Reconstruction versus original source
00:48:29 Move the lantern and inspect the revealed background
00:48:47 Inspect the newly revealed background
00:49:16 Check old shadows and reflections
00:49:45 Save and reopen the editable result
00:50:21 Choose the selection method and save a reusable result
00:51:06 Lesson files and model instructions
00:51:24 Practice and Lecture 6 preview
Follow Lecture 1 for Windows setup. The lesson files include source images, masks, workflows, saved results and model links.
💬 For help, check the pinned comment, join Discord or leave a comment. Support SECourses on Patreon for more guides and resources.
#ComfyUI #GenerativeAI #Inpainting
-
00:00:00 Greetings everyone. Today I am going to show you how to choose exactly where an image changes in
-
00:00:05 ComfyUI. We will paint masks, select objects with words, and edit small regions. Look at the lower
-
00:00:13 right corner of our watercolor from Lecture 3. The model invented a little signature. We will
-
00:00:19 repair that mark while keeping the surrounding painting, then inspect the boundary closely.
-
00:00:29 We will also extend an image, work on a face inside a large photograph,
-
00:00:33 generate a transparent asset, and separate a product scene into editable layers. Each job
-
00:00:39 uses the selection differently. Check out the tutorial description for the chapters
-
00:00:49 and downloadable lesson files. We will work in our familiar ComfyUI installation, then build
-
00:00:55 and compare the image editing graphs. Before we begin, I am updating our existing ComfyUI
-
00:01:03 installation. Lecture 2 explains this routine in detail. We will use the same application folder
-
00:01:08 and virtual environment, and keep our model folders. I am opening the application folder,
-
00:01:17 then typing CMD in its address bar. This opens Command Prompt in the correct directory. Check
-
00:01:23 that the displayed path points to your ComfyUI installation. First I activate the virtual
-
00:01:31 environment. The environment name appears at the prompt. Now I can update this installation without
-
00:01:38 sending the package command to a different Python on the computer. I am running git pull with the
-
00:01:45 fast forward only option. It downloads the current source changes. If Git reports a local conflict,
-
00:01:51 resolve that specific conflict before continuing with the package update. Next I install the
-
00:01:57 requirements with this environment's Python. Keep the installation output visible until the command
-
00:02:03 finishes. Then restart ComfyUI so the running application loads the updated files and packages.
-
00:02:11 The application is back. Our existing models remain available through their configured folders.
-
00:02:17 We will introduce the additional model files when we reach segmentation and image layers,
-
00:02:23 instead of installing unrelated packs. Our first custom node pack will help us edit a
-
00:02:29 small region of a large image. Before installing it, we will save the current installation state,
-
00:02:35 so we have the working versions available for recovery. This Manager build uses the Extensions
-
00:02:42 panel for installing packs. Its snapshot service is available through the local application. I am
-
00:02:48 opening Command Prompt to save a snapshot before changing the installed nodes. The command calls
-
00:03:02 the Manager snapshot service on this ComfyUI address. It saves the installed versions in
-
00:03:07 the user's Manager folder. We will inspect that saved file before going back to the browser.
-
00:03:14 A snapshot records application and pack versions. Keep your workflows and model files as well. Those
-
00:03:21 are separate assets, and you will need them when restoring a complete working setup on another
-
00:03:26 computer. Back in ComfyUI, I am opening Extensions and searching for Crop and Stitch. Choose the pack
-
00:03:35 by lquesada. Its description explains the 2 operations: extract a region around a mask,
-
00:03:41 then place the edited result back. Look at the pack name and version before installing.
-
00:03:47 Several packs contain similar words. We want ComfyUI Inpaint Crop and Stitch,
-
00:03:52 which provides the paired crop and stitch nodes used in this lecture. I am clicking Install for
-
00:03:58 that Registry entry. Wait for installation to finish, then restart ComfyUI. Restarting
-
00:04:04 loads the new Python nodes; refreshing the browser alone cannot load code into an old server process.
-
00:04:19 After the restart, I press R to refresh the node definitions. Now I am opening the node search
-
00:04:25 and looking for Inpaint Crop. The scissors symbol helps identify this pack's displayed node names.
-
00:04:32 The pair is Inpaint Crop and Inpaint Stitch. Use the current nodes from the installed pack. The
-
00:04:38 supplied workflows keep their class and version information, which helps distinguish them from
-
00:04:44 older examples with similar display names. Here is the instruction edit from Lecture 4 beside its
-
00:04:51 original. We asked for a local change, but an edit model can also alter texture or lighting
-
00:04:57 elsewhere. Let us inspect those surrounding details together. Pause and predict: if the
-
00:05:03 model can find a jacket from our instruction, why would we still use a mask? Think about a job where
-
00:05:09 the other objects and background must remain unchanged. A mask gives us an explicit spatial
-
00:05:16 selection. We can use that selection to guide generation, choose a crop, or composite pixels.
-
00:05:22 Those are separate operations even when they use the same painted shape. The noise mask belongs to
-
00:05:28 the sampling process. An explicit image composite happens after decoding. When you need unchanged
-
00:05:34 outside pixels, keep the original destination and place only the accepted patch over it. We will use
-
00:05:41 the visible mask preview throughout this lecture. A white region is selected for these editing and
-
00:05:47 source-compositing nodes. Black is excluded, while grey supplies a partial value to the receiving
-
00:05:53 operation. I am loading our workshop image. The man, the red car and the building give us several
-
00:06:00 clear targets. First we will paint a selection by hand, then compare it with selections made
-
00:06:06 from colour and words. Select the Load Image node and open its mask editor. The base image
-
00:06:13 is the picture underneath. The mask layer stores the selection separately, so painting the mask
-
00:06:18 does not directly recolour the photograph. I am choosing the mask pen and setting hardness to 1.
-
00:06:25 Watch the edge as I paint over part of the jacket. A fully hard brush makes a sharp transition
-
00:06:31 between the selected and unselected area. Brush thickness controls the size of the painted stroke.
-
00:06:41 Use a larger brush for the interior and a smaller one near a boundary. I am keeping
-
00:06:46 the stroke inside the jacket while you watch its outline. If a stroke crosses the boundary, use
-
00:06:54 the eraser to remove that part of the selection. The eraser changes the mask. The base photograph
-
00:07:00 remains available underneath while we correct the painted region. The paint pen is different:
-
00:07:06 it edits the image's colour layer. For this selection exercise we keep the mask pen active.
-
00:07:12 Check the tool and active layer before drawing, especially after switching between editing tasks.
-
00:07:18 I am saving the mask back to the Load Image node and connecting its mask output to Mask to Image.
-
00:07:25 This preview shows the actual single-channel selection that the graph will receive. Notice
-
00:07:31 that we have saved both the original image and the mask. The source remains available for another
-
00:07:37 attempt or for the final pixel composite. We are not replacing the original file with the
-
00:07:42 painted preview. Now I am reopening the editor and changing hardness to 0.2. I will paint a nearby
-
00:07:49 stroke so we can compare its edge with the hard stroke we just made on the same image. The softer
-
00:08:02 stroke includes a wider grey transition. Look at that transition in the mask preview. Its effect
-
00:08:08 depends on the next node: a compositor blends pixels, while Differential Diffusion uses it
-
00:08:14 during sampling. You can adjust brush size and hardness with the editor's brush shortcut. Hold
-
00:08:20 Alt and drag with the right mouse button. Move horizontally for size and vertically for hardness
-
00:08:27 while watching the displayed controls. Use the shortcut when it helps you stay over the area
-
00:08:33 you are painting. For an exact comparison, enter the value in the control and inspect the preview
-
00:08:39 before running the downstream graph. Painting is useful for a specific outline, but this jacket
-
00:08:46 also has a distinctive colour. I am clearing the practice strokes and choosing Color Select so we
-
00:08:52 can select pixels that share that colour. I am clicking the jacket and adjusting the tolerance
-
00:08:58 while watching the mask. Too narrow a selection misses shaded fabric. Too broad a selection can
-
00:09:04 include similarly coloured material elsewhere in the image. Look beyond the main jacket area.
-
00:09:11 Colour selection compares colour, so it can pick an unrelated object with similar values.
-
00:09:16 Remove those unwanted regions with the mask eraser before using the selection for an edit.
-
00:09:51 Paint Bucket follows a connected region around the clicked location. Color
-
00:09:55 Select can find matching colours across the image. Choose between
-
00:09:59 them by inspecting whether you want 1 connected patch or all matching pixels.
-
00:10:46 The mask preview is the final check. Follow the shoulders, sleeves and jacket opening.
-
00:10:51 Save the useful selection, then return to the graph so we can apply the same spatial ideas
-
00:10:56 to the watercolor repair. Here is the original watercolor from the 0.8 LoRA example in Lecture
-
00:11:04 3. I am keeping that source unchanged. The repair will be a separate output, with its own mask and
-
00:11:10 workflow. Let us enlarge the lower right corner. The unwanted handwritten mark sits over the
-
00:11:17 water texture. We want to replace the mark with plausible water while keeping the lighthouse,
-
00:11:22 rocks and surrounding brushwork intact. I am opening the mask editor and painting over the
-
00:11:29 entire mark, including its thin edges. Leave some nearby water visible around the selection,
-
00:11:35 because that context helps the new patch match the existing painting.
-
00:11:47 Save the hard mask and inspect it through Mask to Image. Make sure every unwanted stroke lies
-
00:11:53 inside the white area. A missed fragment outside the selection can survive even when the generated
-
00:11:59 patch looks convincing. We will compare 2 versions with the same source, prompt,
-
00:12:05 seed and sampler settings. The first uses the hard mask. The second grows and softens the
-
00:12:11 selection and applies Differential Diffusion to the model. For this seam experiment we use
-
00:12:17 the Z-Image-Turbo model from Lecture 1. I am opening its matched loader and decoder graph.
-
00:12:23 The watercolor is the source image, rather than a new text-only starting latent. First connect
-
00:12:29 the loaded image to VAE Encode. The matching VAE converts the source pixels into the latent
-
00:12:35 representation used by this model. Keep the image decoder connected to that same matched VAE. Now I
-
00:12:42 am adding Set Latent Noise Mask. Connect the encoded latent to its samples input,
-
00:12:47 then connect our painted mask to its mask input. This attaches the spatial selection to the
-
00:12:53 original latent. The masked latent goes into the sampler's latent image input. The model and text
-
00:13:04 conditioning still connect as usual. Follow those paths together: the prompt describes the fill,
-
00:13:09 and the mask chooses its spatial region. Our prompt describes clear watercolor water continuing
-
00:13:16 the nearby colour and brush texture. We remove the unwanted mark through the selected region,
-
00:13:23 rather than asking the model to redesign the lighthouse or the whole composition. I am
-
00:13:29 keeping the seed fixed and using the same sampler settings for both versions. Denoise controls the
-
00:13:36 amount of regeneration within this path. We will read the selected values beside the results when
-
00:13:41 comparing them. The original source latent still carries image information. As denoise increases,
-
00:13:48 more of the selected detail can be replaced. Choose the value by inspecting whether the
-
00:13:53 unwanted mark remains and whether the new water fits. After sampling, VAE Decode turns the latent
-
00:14:01 into pixels. I am saving this decoded result separately. Before we accept it, we will inspect
-
00:14:06 the patch and compare the surrounding picture against the original. I am also keeping the
-
00:14:12 original image connected to the final composite's destination. The edited image will be its source.
-
00:14:18 We will connect the accepted mask after choosing the version we want to keep. The hard-mask graph
-
00:14:25 is ready. I am starting the run now. Watch the sampler progress and completion, then we
-
00:14:30 will enlarge the lower right patch to inspect the replaced mark and the edge of the repair.
-
00:14:46 Here is the decoded result. Start with the place where the signature was, then follow the boundary
-
00:14:52 around that patch. Compare the water's colour, texture and stroke direction with the surrounding
-
00:14:58 original image. A hard boundary can reveal a change even when the unwanted object is gone.
-
00:15:05 Look for a sudden shift in colour or texture. We will compare this version with a graded selection
-
00:15:11 under the same generation settings. Keep the hard-mask result visible in the comparison. We
-
00:15:17 will preserve this output and its recipe, then change only the mask treatment and model patch
-
00:15:24 needed for the next version of the experiment. Back in the graph, I am adding Grow Mask after
-
00:15:30 the painted selection. A small positive expansion covers the edge around the unwanted mark. Negative
-
00:15:36 expansion would shrink the selection instead, which could expose missed fragments. I am
-
00:15:42 setting the expansion to 8 pixels for this source. Watch the mask preview as the white region grows.
-
00:15:49 The useful distance depends on the image and the object boundary, so judge it in pixels here. Next
-
00:15:55 convert the mask to an image and pass it through Blur. This creates a graded transition around the
-
00:16:01 expanded region. Then Image to Mask converts the red channel back into a mask for the latent node.
-
00:16:14 The blur radius controls the neighbourhood, and sigma controls how the blur is distributed. We
-
00:16:20 keep the settings visible beside the preview. The goal is a smooth boundary while still covering the
-
00:16:26 full unwanted mark. Now I am placing Differential Diffusion between the model loader and the
-
00:16:32 sampler. It is a model patch in this graph. The graded mask still enters Set Latent Noise Mask
-
00:16:38 through the latent path. Follow both connections at once. The mask supplies spatial values,
-
00:16:58 and Differential Diffusion interprets them during the denoising schedule. White regions participate
-
00:17:03 earlier; darker grey regions join later as the schedule progresses. We keep the original source,
-
00:17:10 prompt, seed and sampler values from the hard-mask run. The change we are testing is the grown and
-
00:17:17 blurred selection with Differential Diffusion. I am starting that second run now. After decoding,
-
00:17:25 the new result is saved under its own name. Keeping both outputs makes the comparison
-
00:17:31 reversible. We can choose the better patch without losing the original mask,
-
00:17:35 image or first generation. I am placing the original and repaired images side by side with
-
00:17:41 clear labels. First compare the full painting, then concentrate on the lower right water. The
-
00:17:47 repair should serve the composition as well as the enlarged patch. Now let us compare the 2
-
00:17:54 repair versions at the same scale. Follow the edge of each selection and inspect the water texture.
-
00:18:01 Choose the version whose patch blends more naturally with the surrounding brushwork. The
-
00:18:06 aligned slider lets us inspect the same location before and after. I am moving it slowly across
-
00:18:12 the repaired mark. Watch a fixed feature near the boundary so small shifts remain easy to see. The
-
00:18:19 enlarged comparison reveals small dark fragments in both initial repairs. The mask covers the
-
00:18:25 writing, but this denoise setting still preserves too much of its structure. I am keeping those
-
00:18:31 results as evidence. I am raising denoise to 1 in the hard-mask version. The source, prompt,
-
00:18:38 seed and remaining sampler settings stay the same. This gives the selected area more freedom
-
00:18:43 to replace the remaining fragments. The graded version uses the same higher denoise value. Its
-
00:18:57 mask treatment and Differential Diffusion remain the comparison variables. After both files are
-
00:19:03 saved, we can judge the texture and boundary at matching scale. Once we choose the patch,
-
00:19:18 connect that edited image to the composite source and the original to its destination. The accepted
-
00:19:24 mask selects the patch. Outside that selection, the destination supplies the original pixels. I
-
00:19:39 am saving the final composite and reopening it. Now compare the outside region against
-
00:19:44 the source. A 0 difference outside the accepted mask means those saved pixels are identical to
-
00:19:50 the original painting. The grey boundary is part of the accepted blending region. Measure outside
-
00:19:56 the complete mask support, including that soft edge. Otherwise a deliberately blended edge can
-
00:20:03 be mistaken for an unwanted change outside the repair. Return to the full composition before
-
00:20:09 finishing. The lighthouse and rocks give us context, while the repaired corner should
-
00:20:14 read as continuous water. Keep the original, both masks and the chosen repair in the lesson folder.
-
00:20:22 Let us make the grey values easier to understand with a ramp. The mask moves gradually from black
-
00:20:27 on one side to white on the other. We will use it on the same masked latent path. I am
-
00:20:41 previewing the ramp before connecting it to the sampler. Black, grey and white now occupy large
-
00:20:47 visible regions. That makes the change across the schedule easier to inspect than a narrow feather
-
00:20:53 around a small patch. With Differential Diffusion connected, the white end participates through more
-
00:21:00 of the denoising process. Darker values join later. The grey mask therefore controls when
-
00:21:06 different spatial regions begin changing during this particular sampler schedule.
-
00:21:12 The strength control blends the patch's behaviour. We will keep it at 1 for this demonstration so
-
00:21:18 the thresholded schedule is clear. The result still depends on the selected model, source and
-
00:21:24 denoise settings. I am starting the ramp run with a visible change in the prompt. Watch the output
-
00:21:31 from the black end through the middle to the white end. Compare how much source structure remains
-
00:21:37 across that transition. Here is the result beside the ramp. Move your attention along the gradient
-
00:21:46 and compare corresponding image regions. The relationship is easier to read when the source,
-
00:21:51 mask and output are aligned at the same scale. This is useful when the centre of a repair needs
-
00:21:59 a strong change while its boundary should stay closer to the source. Shape the mask for the edit,
-
00:22:05 then inspect whether the generated transition actually fits. Now we will turn spatial selection
-
00:22:11 outward. I am loading the workshop scene into Image Pad for Outpaint. Padding creates
-
00:22:16 a larger canvas and a mask for the area that did not exist in the original picture. I am
-
00:22:23 adding space to the left side and keeping the other sides unchanged. Look at both outputs:
-
00:22:28 the padded image provides the context, and the mask identifies the new area we want the model to
-
00:22:34 fill. Feathering gives the boundary a transition region. We also keep the final dimensions aligned
-
00:22:41 to the grid used by our Qwen 2.1 workflow. Padding increments and the model's required alignment are
-
00:22:49 separate settings. The padded image goes into the matched Qwen instruction graph. Our prompt asks
-
00:22:55 it to continue the street, building and lighting into the new area. It uses the existing scene as
-
00:23:01 the reference for that extension. I am starting the outpaint. When it finishes, inspect the old
-
00:23:07 and new sides together. Follow the pavement, roofline and wall texture across the boundary,
-
00:23:14 because an extension needs continuity as well as attractive new content. Here is the wider canvas.
-
00:23:36 I am bringing the boundary into view at a readable scale. Compare the direction of lines, the size of
-
00:23:42 repeated features, and the brightness on both sides of the original edge. To preserve the
-
00:23:48 original region exactly, use the padded original as the composite destination and the generated
-
00:23:54 extension as its source. The pad mask selects the new region and its chosen transition edge.
-
00:24:02 I am saving that composite and comparing the original region again. Choose a modest extension
-
00:24:07 when a wider one loses the scene's perspective. You can grow the canvas in stages while keeping
-
00:24:14 each accepted source available. Manual masks work well for a small repair. For an entire car,
-
00:24:21 jacket or window, we can ask a segmentation model for the selection. We will use the native
-
00:24:26 SAM3 detection node in ComfyUI. The model download belongs in the checkpoints folder. This checkpoint
-
00:24:33 includes the model and its text encoder, so we load it with Load Checkpoint. It uses a different
-
00:24:39 component set from our image generation graph. I am opening the model's download
-
00:24:45 page and selecting the checkpoint file. Keep its complete filename. Once the download finishes,
-
00:24:51 place it in the checkpoints folder that this ComfyUI installation actually searches.
-
00:25:05 After refreshing the model list, select that checkpoint in Load Checkpoint. Connect its
-
00:25:10 model output to SAM Detect, and its clip output to the text encoding node. Our workshop image
-
00:25:16 supplies the image input. The selection prompt describes an object to find. It does not ask
-
00:25:28 the image model to redraw that object. The detection result is a mask we can inspect,
-
00:25:33 edit or pass into the other workflows. This installed text encoder uses a 32-token context.
-
00:25:40 Keep the phrase short and specific. We will use the red car, the jacket, and every window,
-
00:25:46 instead of a long paragraph describing the whole scene. First I am entering the red
-
00:25:51 car and running the detection graph. The mask output goes through Mask to Image so we can
-
00:25:57 inspect it. Compare its silhouette with the car before using it in an edit. Look at the wheels,
-
00:26:07 roof and glass boundaries. A detected mask is a starting selection. If part of the surrounding
-
00:26:12 pavement is included, or a required edge is missing, correct the mask before compositing the
-
00:26:18 image. Now I am changing only the phrase to the jacket. The same image and model stay connected.
-
00:26:24 Watch how the selected region moves from the car to the man's clothing without us painting a new
-
00:26:30 outline. We can use this mask as the starting point for a clothing edit. Inspect the collar
-
00:26:43 and sleeves, then choose the amount of growth and feathering for the receiving workflow. Selection
-
00:26:49 and generation remain separate steps. For windows, I am enabling individual masks. This returns
-
00:26:56 separate detected instances instead of combining every selected window into 1 mask. We can inspect
-
00:27:03 the batch 1 image at a time before choosing a particular window. This installed encoder keeps
-
00:27:09 1 detection per phrase by default. I am adding a colon and an upper count to the window phrase.
-
00:27:15 That allows several matching windows to pass into the individual mask batch. The count is a limit,
-
00:27:22 not a request to invent extra windows. We keep the phrase concise and run detection again. Compare
-
00:27:28 each returned mask with the visible building and keep their order clear in the saved files.
-
00:28:00 Threshold controls which detections are accepted. A higher value keeps stronger matches;
-
00:28:06 lowering it can admit more candidates. Change it only while inspecting whether the extra selection
-
00:28:12 belongs to the object you actually want. The refinement setting works on the mask boundary
-
00:28:18 after detection. Inspect thin frames and gaps at a closer view. Keep a useful mask separately
-
00:28:24 so a later parameter change does not replace the selection you already accepted. Now let
-
00:28:30 us edit a face inside a larger photograph. This source is a photograph by Toan Van,
-
00:28:36 provided with its credit in the lesson files. We will keep the original and save the edited
-
00:28:41 versions separately. I am setting the image's long edge to 4096 pixels. The same saved source
-
00:28:49 feeds both comparisons. Look at the face area relative to the whole canvas before we decide
-
00:28:54 how much of it to process. Our instruction will add round eyeglasses while keeping the
-
00:29:02 man's expression and the rest of the scene. We will first send the whole picture through Qwen,
-
00:29:08 then edit a crop around the face with the same instruction. I am painting the face
-
00:29:14 selection and leaving surrounding hair and skin as context. The mask defines where we want the
-
00:29:20 final change. We will use that same region when checking the outside pixels after stitching.
-
00:29:43 In the whole-frame graph, the entire photograph enters Text Encode Qwen-Image 2.1. Its resolution
-
00:29:50 control sets the reference pixel budget while preserving the image's aspect ratio on the
-
00:29:55 required grid. At this budget, the face occupies only part of the resized reference. The rest of
-
00:30:02 the pixels describe clothing and background. Keep that distribution in mind when we compare the face
-
00:30:08 with a separately enlarged crop. I am entering the glasses instruction and keeping the seed fixed.
-
00:30:15 The sampler, model and text remain visible in the graph. We will preserve these values for
-
00:30:21 the crop comparison so the changed processing region is clear. I am starting the whole-frame
-
00:30:27 run. We will read its actual execution time from the application when it finishes. Keep
-
00:30:32 the first model-loading work separate from the repeated sampling work when interpreting
-
00:30:38 that time. Here is the whole-frame edit. Inspect the glasses, the eyes and the surrounding hair,
-
00:30:46 then look at the jacket and background. A local instruction can still produce other changes when
-
00:30:51 the complete picture is regenerated. I am saving this version before changing the graph. It is the
-
00:30:58 whole-frame comparison, with its original prompt and settings. Next we will give the
-
00:31:03 face more of the model's working image area. Add Inpaint Crop after the loaded photograph
-
00:31:13 and face mask. The crop node returns the extracted image, its mask, and a stitcher
-
00:31:18 object. That object carries the information needed to place the edited crop back correctly.
-
00:31:39 Connect the cropped image to the Qwen reference input. Keep the crop mask visible in a preview.
-
00:31:45 The model now receives the local region and its surrounding context instead of the full photograph
-
00:31:51 at the same working budget. Context controls how much surrounding image the crop includes. Too
-
00:32:04 little can hide the hairstyle or lighting cues needed by the edit. Too much spends the working
-
00:32:10 area on background and makes the face smaller again. I am increasing the context around the
-
00:32:16 face until the crop includes its immediate surroundings. Watch the cropped preview as
-
00:32:22 the region changes. Keep both the target and the useful nearby details within this view.
-
00:32:35 The output size controls the working dimensions of the crop. We choose a size that suits the Qwen
-
00:32:41 graph and keep its required alignment. The final photograph keeps its original canvas size after
-
00:32:47 stitching. Mask expansion and blend width serve different roles. Expansion changes the selected
-
00:32:54 area. The blend controls the transition when the edited crop returns to the original. Inspect both
-
00:33:00 the crop preview and the final edge. Now connect the crop's stitcher output to Inpaint Stitch,
-
00:33:07 and the decoded edited crop to its image input. The node uses the saved placement
-
00:33:12 information to return that local result to the full photograph. I am keeping the
-
00:33:18 same glasses instruction and seed as the whole-frame run. The crop changes what the
-
00:33:23 model sees at this working size, so compare the resulting face as well as the time taken.
-
00:33:29 The graph is connected, and I am starting the crop run. After the model finishes, follow the edited
-
00:33:35 image into the stitch node. The saved output should have the full photograph's dimensions
-
00:33:41 and the local edit in place. Here is the stitched result. Inspect the glasses and eye area first,
-
00:33:54 then follow the blend around the face. Look for changes in skin tone, hair detail or sharpness
-
00:34:00 that make the inserted region stand out. Let us place both edited faces beside the original at the
-
00:34:07 same scale. The labels identify the whole-frame route and the crop route. Compare the rims,
-
00:34:12 pupils, hairline and expression before choosing the result to keep. I am enlarging the same region
-
00:34:19 to 400%. This makes small differences visible. Judge the shapes and consistency with the source;
-
00:34:26 sharper invented texture is not automatically a more faithful face. The displayed times come from
-
00:34:33 these actual runs. Keep the hardware, working size and model-loading conditions beside the
-
00:34:38 comparison. A crop can change both the amount of processing and the detail available to the
-
00:34:44 model. Now compare the saved outside region with the original photograph. If the stitch
-
00:34:50 has changed pixels beyond the accepted blend mask, use the original as the destination of
-
00:34:56 an explicit final composite to restore them. I am saving that final version and checking the
-
00:35:12 difference again. The accepted edit includes the chosen blend edge. Outside its complete support,
-
00:35:19 the original supplies the pixels that we want to preserve exactly. Return to the full photograph
-
00:35:38 before finishing. A convincing close view should also fit the original composition and lighting.
-
00:35:44 Keep both comparison outputs, the face mask and the final workflow so you can repeat the
-
00:35:50 same operation. Now we will create an object that can be placed over another image. Qwen-Image 2.1
-
00:36:06 supports a native transparent output through its matched image decoder. We will generate a
-
00:36:11 lantern and inspect its actual alpha channel. I am opening the transparent-output workflow with
-
00:36:19 the same Qwen 2.1 component set. The prompt asks for an isolated brass lantern with a transparent
-
00:36:25 background. The saved image needs to retain all 4 channels. The red, green and blue channels store
-
00:36:32 colour. Alpha stores opacity. A fully opaque point has alpha 1, while a transparent point
-
00:36:38 has alpha 0. Intermediate values represent a partially transparent edge or material.
-
00:36:44 I am starting the lantern generation. When it finishes, we will view the asset over both light
-
00:36:50 and dark backgrounds. This makes an unwanted solid background or a coloured edge easier to spot. Here
-
00:36:57 is the lantern over the light background. Inspect the handle, its thin metal parts and the glass.
-
00:37:03 Now switch to the dark background and inspect the same boundary, keeping the asset at the
-
00:37:09 same scale. A checkerboard drawn into the colour image would stay visible on both backgrounds. Real
-
00:37:17 alpha lets the new background show through the transparent pixels. We will inspect the alpha
-
00:37:23 preview as well as the composed appearance. I am saving the lantern as a PNG, then loading that
-
00:37:33 saved file back into the graph. This checks the file we will actually reuse. A preview
-
00:37:38 on the screen is useful only if the saved asset retains its transparency. Connect the reloaded
-
00:37:46 image's mask output to Mask to Image. Notice the convention used by Load Image: transparent areas
-
00:37:52 are white in this mask. It is the inverse of the alpha opacity stored in the PNG.
-
00:38:03 For Image Composite Masked, white selects the source. We therefore add Invert Mask
-
00:38:08 before using this transparency mask to place the lantern. The lantern becomes selected,
-
00:38:14 and the empty background becomes excluded from the source. Follow the 2 paths together.
-
00:38:26 The image output carries the lantern colours, and the inverted mask carries its opacity selection.
-
00:38:32 Those inputs meet at the compositor, where the destination supplies the background image. Join
-
00:38:49 Image with Alpha uses the matching inverted-mask convention. Connecting the loader's mask there
-
00:38:54 rebuilds the original opacity. Read each node's convention instead of assuming every input called
-
00:39:00 mask or alpha uses the same polarity. The direct alpha channel of a 4-channel image is opacity. If
-
00:39:15 we extract it with Image to Mask, opaque areas are white. Keep that route distinct from the
-
00:39:21 transparency mask returned by the file loader. I am loading the background image into the composite
-
00:39:32 destination and the lantern into its source. The opacity selection goes into the mask input.
-
00:39:38 We can now position this saved object without asking a model to regenerate the background.
-
00:39:56 The horizontal and vertical offsets choose where the source begins on
-
00:40:01 the destination canvas. I am moving the lantern into place while keeping
-
00:40:05 its dimensions visible. Inspect the contact point and the surrounding space as it moves.
-
00:40:15 Source resizing changes the object scale. Keep the image and opacity mask aligned when you resize
-
00:40:20 them. A mismatched mask can cut into the lantern or leave a displaced edge around its silhouette.
-
00:40:45 Now inspect the final boundary over this background. The generated glass and metal
-
00:40:49 may need different opacity detail. A segmentation mask selects visible regions; the generated alpha
-
00:40:56 can include partial transparency inside the asset itself. We can compare the lantern's
-
00:41:02 generated alpha with a segmentation selection of the same object. Look especially at the
-
00:41:08 handle opening and glass. Choose the selection that preserves the appearance needed by this
-
00:41:14 particular composite. I am saving the composed result while retaining the separate lantern
-
00:41:31 PNG. Keeping the asset separate lets us move or colour-match it later. The background remains
-
00:41:37 the original destination outside the lantern's accepted opacity region. The lantern also needs
-
00:41:57 to fit the background's colour and lighting. I am adding Color Transfer to the source branch,
-
00:42:02 with the background as its reference. The mask and placement stay available while we compare
-
00:42:08 the colour change. The method controls how colour statistics are matched, and strength blends the
-
00:42:25 correction. Start with a moderate strength and inspect the brass, glass and shadows. A
-
00:42:31 stronger numerical setting is useful only when it improves this scene. Apply the correction before
-
00:42:42 the final masked composite, so the selected asset changes while the original background remains the
-
00:42:48 destination. Keep the opacity mask aligned with the corrected colour image at the same dimensions.
-
00:43:02 Let us enlarge the edge again. In straight alpha, colour is stored independently of
-
00:43:07 opacity. In premultiplied alpha, colour has already been multiplied by opacity. Mixing
-
00:43:13 those interpretations can create a dark or bright fringe. Use the alpha interpretation
-
00:43:19 expected by the receiving application, then inspect the saved result over light and dark
-
00:43:25 backgrounds. If the edge changes brightness unexpectedly, check that interpretation before
-
00:43:30 painting away useful transparent detail. I am reopening the final PNG and comparing the
-
00:43:42 background outside the accepted region. Keep the original destination, the transparent source and
-
00:43:47 the composite together. That gives you an editable asset instead of only a flattened final picture.
-
00:44:07 Our last example goes beyond cutting out an object. We will ask Qwen-Image-Layered
-
00:44:13 to decompose this product scene into an ordered set of images. The foreground lantern overlaps
-
00:44:18 a travel case and the tabletop behind it. Layered uses its own model, text encoder and RGBA decoder.
-
00:44:26 The Qwen 2.1 files from the previous example are a different component set. I am opening the official
-
00:44:32 Layered workflow and its download information. Download the diffusion model into diffusion
-
00:44:38 models, the text encoder into text encoders, and the decoder into the VAE folder. Keep the complete
-
00:44:44 filenames visible, then refresh the application and select those exact files in the loaders.
-
00:45:13 We are using the mixed precision model listed with this template. Its files have different
-
00:45:19 memory and storage requirements from the earlier editing models. Check the download size and free
-
00:45:25 storage before starting. I am loading our product scene into the workflow. We will keep its original
-
00:45:33 pixels as a comparison. The model creates a reconstructed layered version, so we will
-
00:45:38 inspect both the reconstruction and each layer it produces. The working resolution sets the
-
00:45:45 image size used for decomposition. The layer count controls how many separate layers we request. Use
-
00:45:51 a small, understandable scene first, then inspect whether its objects are separated usefully.
-
00:45:58 The template keeps the generated full-image reconstruction separately from the extracted
-
00:46:03 layer batch. We will preserve that order when decoding and saving. A different batch position
-
00:46:09 can mean a different object or background layer. I am starting the decomposition run now. Once it
-
00:46:16 finishes, we will inspect the full reconstruction, preview the alpha of each layer, and recombine
-
00:46:22 them before moving the foreground object to another position. Here is the reconstructed
-
00:46:38 image beside the original product scene. Compare the lantern shape, travel case and wood grain.
-
00:46:44 Keep any changed details visible as we decide how useful this decomposition is for the planned edit.
-
00:46:52 Now I am opening the layers in their saved order. Look at the colour and alpha together. An isolated
-
00:46:58 layer can contain transparent areas around its object and newly generated content where another
-
00:47:04 object previously covered it. The background layer comes first in the composite. Place the
-
00:47:10 next layer over it using that layer's opacity, then continue through the stack. Changing this
-
00:47:16 order can place a background element in front of the lantern. I am reconnecting the layers in that
-
00:47:30 order and viewing the composite. Compare it with the model's reconstruction, then with the original
-
00:47:36 source. Those 2 comparisons answer different practical questions about the layer output.
-
00:47:50 Matching the reconstruction checks our layer order and compositing path. Comparing against
-
00:47:55 the source shows what the model changed while decomposing the scene. Inspect the
-
00:48:01 table texture and object edges before making another edit. Keep each saved
-
00:48:06 layer as an RGBA PNG. A flattened image loses the independent opacity and placement controls. The
-
00:48:13 numbered filenames in the lesson folder preserve the order used by this recomposition graph. Now
-
00:48:29 I am changing the horizontal position of the foreground lantern layer. The background and
-
00:48:34 travel case remain in their own branches. We can move this 1 object without regenerating the entire
-
00:48:41 composite again. Watch the area where the lantern used to be. Some of that background was hidden in
-
00:48:52 the original photograph. The layered model had to infer content there, so inspect the newly revealed
-
00:48:58 wood and travel case carefully. Segmentation selects pixels that were visible in the source.
-
00:49:05 Layer decomposition can also generate the content needed behind an occluding object.
-
00:49:10 This is why moving a layer is a stronger test than viewing a stationary cutout. Look at the lantern's
-
00:49:17 contact with the table after the move. A shadow or reflection can remain in another layer or at the
-
00:49:23 old position. Decide which layers need to move together so the edited scene remains coherent.
-
00:49:29 I am comparing the original placement and moved version side by side. Inspect the old position,
-
00:49:36 the new position and the overall balance. Keep the separate layers so you can revise
-
00:49:41 the placement without starting the decomposition again. The final composite is saved under a new
-
00:49:48 name. I am reopening it and then reopening the layered workflow. The saved inputs,
-
00:49:53 ordered layers and placement values remain available for another edit after this session.
-
00:50:21 We have repaired the watercolor mark, extended a scene, selected objects with words,
-
00:50:27 and edited a local face region. The same spatial question runs through all of them:
-
00:50:32 which pixels should this operation affect? Use a painted or segmented mask when you need an
-
00:50:38 explicit region. Give a local edit enough surrounding context, inspect its boundary,
-
00:50:43 and use the original as the final composite destination when outside pixels must stay
-
00:50:49 exact. Use a transparent asset for independent placement, and use layer decomposition when you
-
00:50:56 need separately editable parts of a scene. Inspect the revealed background after moving an object,
-
00:51:02 because that is where inferred content becomes visible. The downloadable files
-
00:51:07 include the source images, masks, workflows and saved results. Keep the model links and folder
-
00:51:14 instructions with them. You can follow these graphs with an image and edit of your own.
-
00:51:24 In Lecture 6 we will add structural control, using maps that describe the shapes and
-
00:51:29 composition we want the model to follow. Try 1 local repair with today's workflow,
-
00:51:34 and inspect both the patch and the untouched surroundings. Thank you for watching. If this
-
00:51:40 lecture helped you, please like the video and subscribe to SECourses. You can use
-
00:51:46 the chapters in the description to return directly to the technique you need next.